Apple Eyes AI Compression Tech to Speed Up iPhone Siri
Apple is evaluating PrismML's AI compression technology, which could allow powerful AI models to run directly on iPhones while using 15x less memory…
Apple is in talks with PrismML, a startup backed by Khosla Ventures, about embedding more powerful AI directly into iPhones without relying on cloud servers. The company's compression technology could reshape how Siri works on iPhone 15 and newer models.
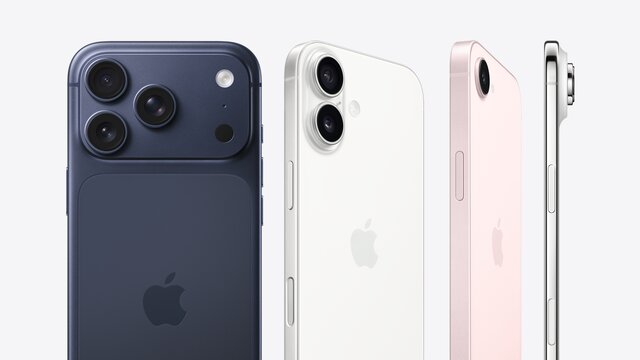
PrismML publicly released compressed versions of Alibaba's open-source Qwen AI model this week, shrinking it from roughly 54 GB to less than 4 GB—a 93 percent reduction. The startup says all 27 billion parameters of the model can now run on an iPhone 15 or newer while using up to 15x less memory than conventional approaches.
"They're really evaluating our technology right now," PrismML CEO Babak Hassibi told CNBC of Apple's interest. He described the discussions as early-stage but said "things are progressing nicely."
The move addresses a core challenge for Apple's AI ambitions. Most capable AI models demand substantial computational resources—typically handled by cloud datacenters. Processing AI on-device instead could speed up Siri and keep user requests from being sent to Apple's servers, a privacy advantage Apple has emphasized as iOS 27 rolls out.
Apple did not respond to requests for comment. The Information first reported the PrismML developments.
Timing Aligns With Siri Overhaul
The talks come as Apple opened the public beta of iOS 27, giving iPhone owners their first broad access to a long-delayed Siri redesign. Apple is positioning the assistant to compete with OpenAI's ChatGPT and Anthropic's Claude while keeping more personal information processed locally on the device.
Smaller, compressed AI models are critical to that strategy. Current large language models running on remote servers introduce latency and raise privacy concerns—every interaction gets logged, analyzed, and potentially retained. Running inference on-device eliminates that friction.
PrismML's approach uses quantization and other compression techniques to strip down models without catastrophic loss of capability. If real-world testing confirms the startup's claims on speed and accuracy, the technique could shift how Apple distributes AI workloads across its ecosystem.
Broader Implications for Memory and Compute
The breakthrough could ripple across Apple's supply chain. Devices capable of running compressed 27-billion-parameter models locally might need less cloud compute spending and could require different memory configurations. Still, analysts caution that AI adoption will continue driving demand for chips and datacenter capacity regardless.
Apple's settlement of a $250 million lawsuit over delayed iPhone 16 and iPhone 15 AI features adds urgency to delivering on-device intelligence. The suit alleged the company misled customers by advertising AI capabilities that weren't ready at launch; first features shipped in iOS 18.1, five weeks after the phones arrived. Eligible buyers could receive payouts between $25 and $95 per device.
On August 13, a court order accelerated the settlement's timeline by approximately seven months, moving the final approval date forward. An Apple spokesman had previously said the company "resolved this matter to stay focused on doing what we do best, delivering the most innovative products and services to our users."
Whether PrismML's technology makes it into production remains uncertain. Hassibi noted it's unclear where the early-stage talks will lead. But the timing—with iOS 27 in public beta and Siri facing stiff competition from cloud-native assistants—suggests Apple is scrambling to shift more AI workload onto the device itself.